← All projectsDESIGN IN DETAIL / P157

Speech Runtime.

Text, voice and output routing together.

Explore the story
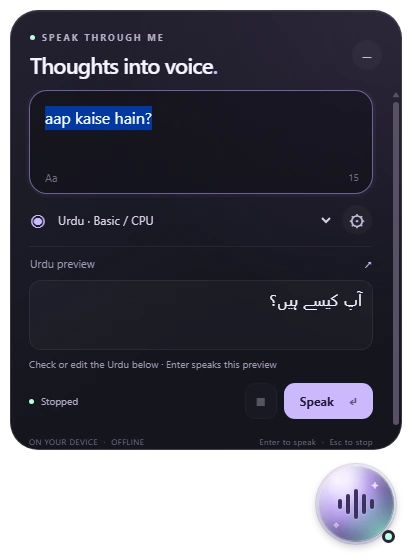
Saved speech-tool interface with typed Roman Urdu, an Urdu preview, voice selection and a Speak button.
Existing saved interface preview. The sample phrase is generic; audio generation and the current application build have not been runtime-tested in this portfolio review.
01 / THE IDEA

A closer
look.

Give speech generation a practical desktop path from typed input to audio output.

02 / DESIGN APPROACH

From intention
to experience.

The interface brings text entry and voice selection into one tool. Worker-based conversion and playback code handle output-device routing, resampling and cancellation around existing speech models.

01

Prepare the speech

Typed content and voice selection provide the starting point for the generation workflow.

02

Choose the destination

Output-device controls connect generated speech to the intended audio route.

03

Control playback

The desktop workflow separates generation and playback workers and supports cancellation.

03 / THE VISUAL STORY

The work,
in full.

Explore the complete compositions and interface states. Select any image for a closer look.

VIEW 01 / 01

Opening view

Saved speech-tool interface with typed Roman Urdu, an Urdu preview, voice selection and a Speak button.

Saved speech-tool interface with typed Roman Urdu, an Urdu preview, voice selection and a Speak button.
Existing saved interface preview. The sample phrase is generic; audio generation and the current application build have not been runtime-tested in this portfolio review.
04 / THE DETAILS

What brings
it together.

Structure, interaction and visual decisions that give the work its character.

Design decisions

  • Text and voice selection
  • Audio-device routing
  • Cancellation controls

Project components

  • Documented production workflow
  • Screen-state artwork
Production notes & credits

RoleConfirm interface design, worker orchestration, audio routing, model integration and assisted coding contributions.

AssetsCredit model providers, Kokoro ONNX, transliteration code/data, voice assets and libraries. Do not claim training or ownership of the underlying models.

StatusStatic source and documentation reviewed; audio quality, timing and current runtime unverified.

Image notes

  • Existing saved interface preview. The sample phrase is generic; audio generation and the current application build have not been runtime-tested in this portfolio review.
HAVE SOMETHING IN MIND?Let’s make it
an experience.